Use your data to improve your agents

Lucidic AI is a training platform for AI agents. It uses your production data to train custom models and harnesses that lower cost per task and handle more of them correctly.

Book a demo

Companies optimizing agents with Lucidic

Philosophy

The best people learn from every experience. We’re building a world where AI agents do too. Every company already has that experience in its data, and Lucidic uses it to improve their agents, in both the model and the harness

Improvement

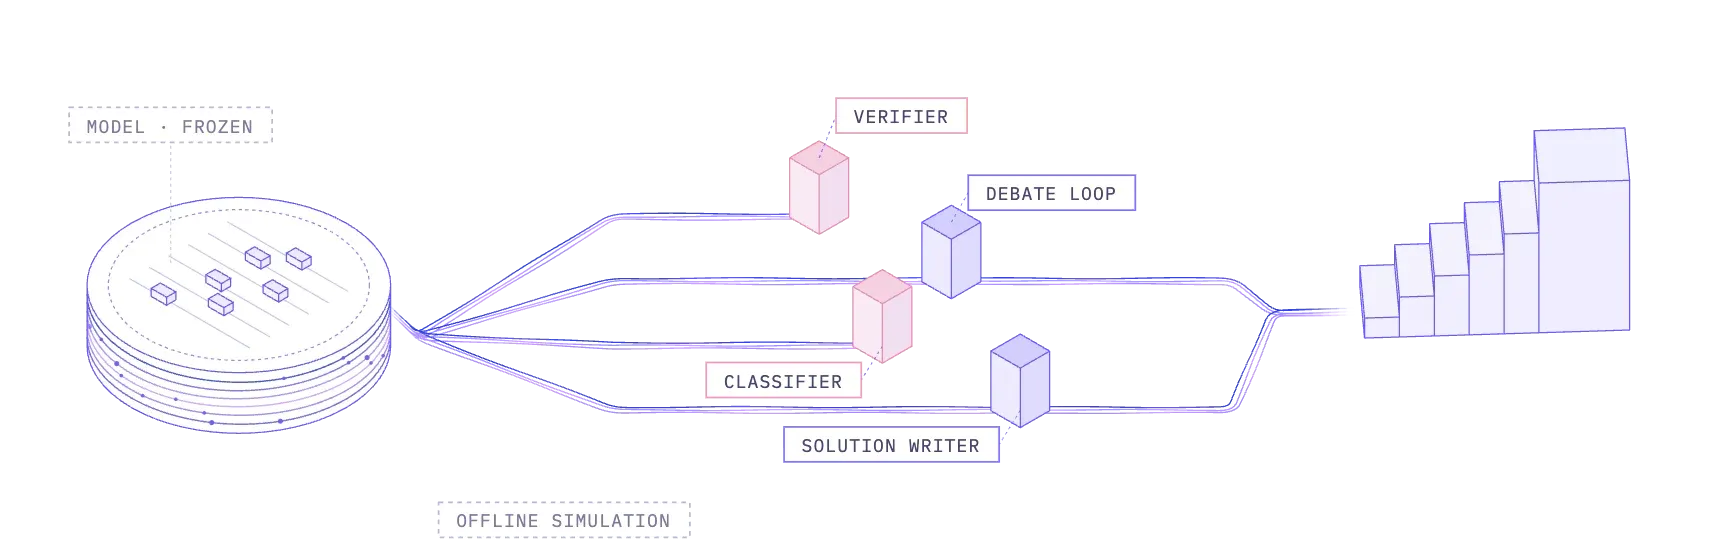
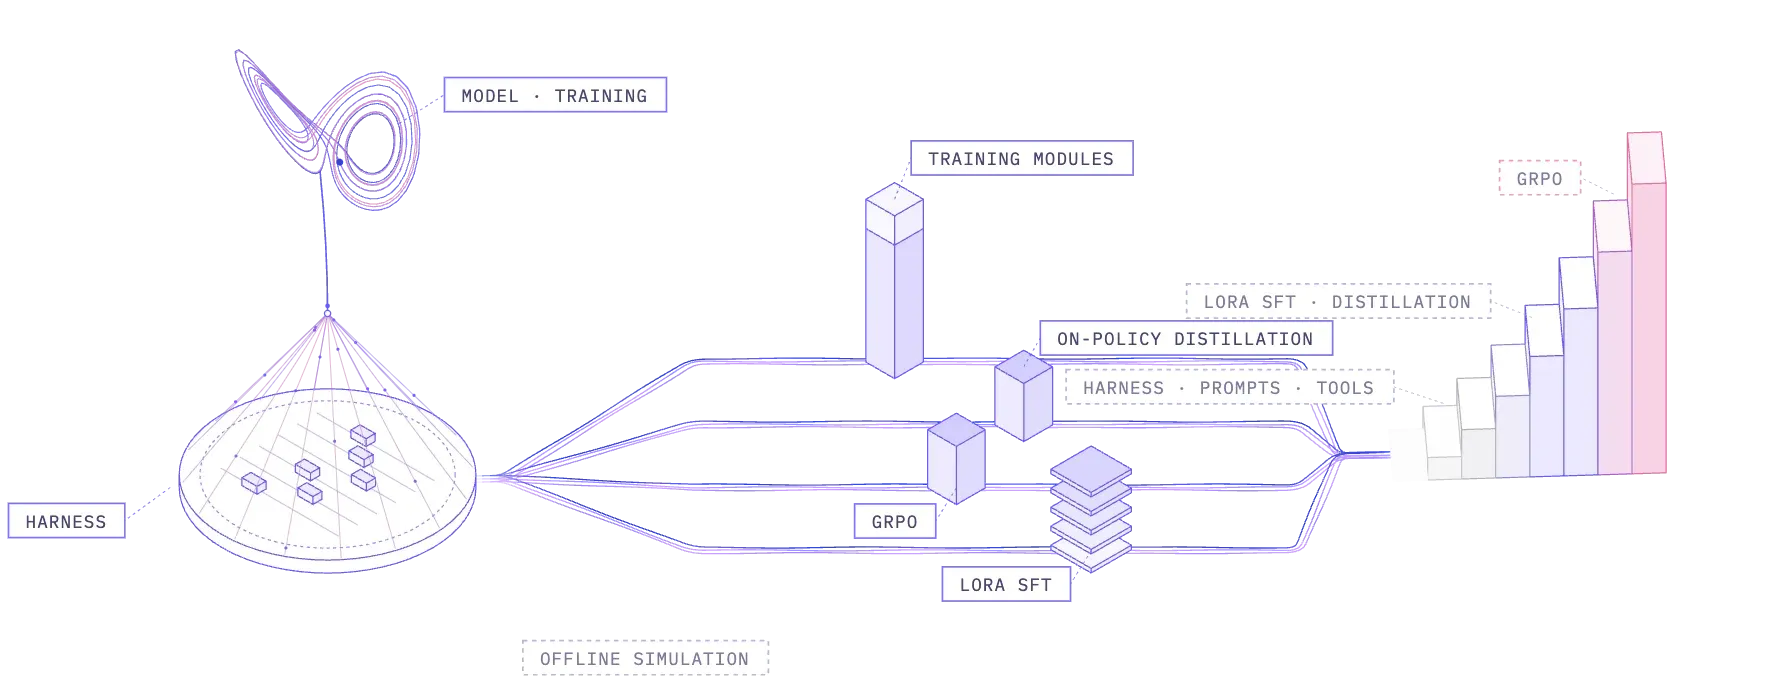
Two ways to improve your agent: optimize the harness, or train the model and the harness together

Diagram: the model stays frozen while training modules (verifier, classifier, debate loop, solution writer) are added around it and tested in offline simulation.
  1. Define your training parameters

    Choose which parts of your agent can change: prompts, memory, tools, or new steps. Everything else stays fixed.

  2. Launch a training job

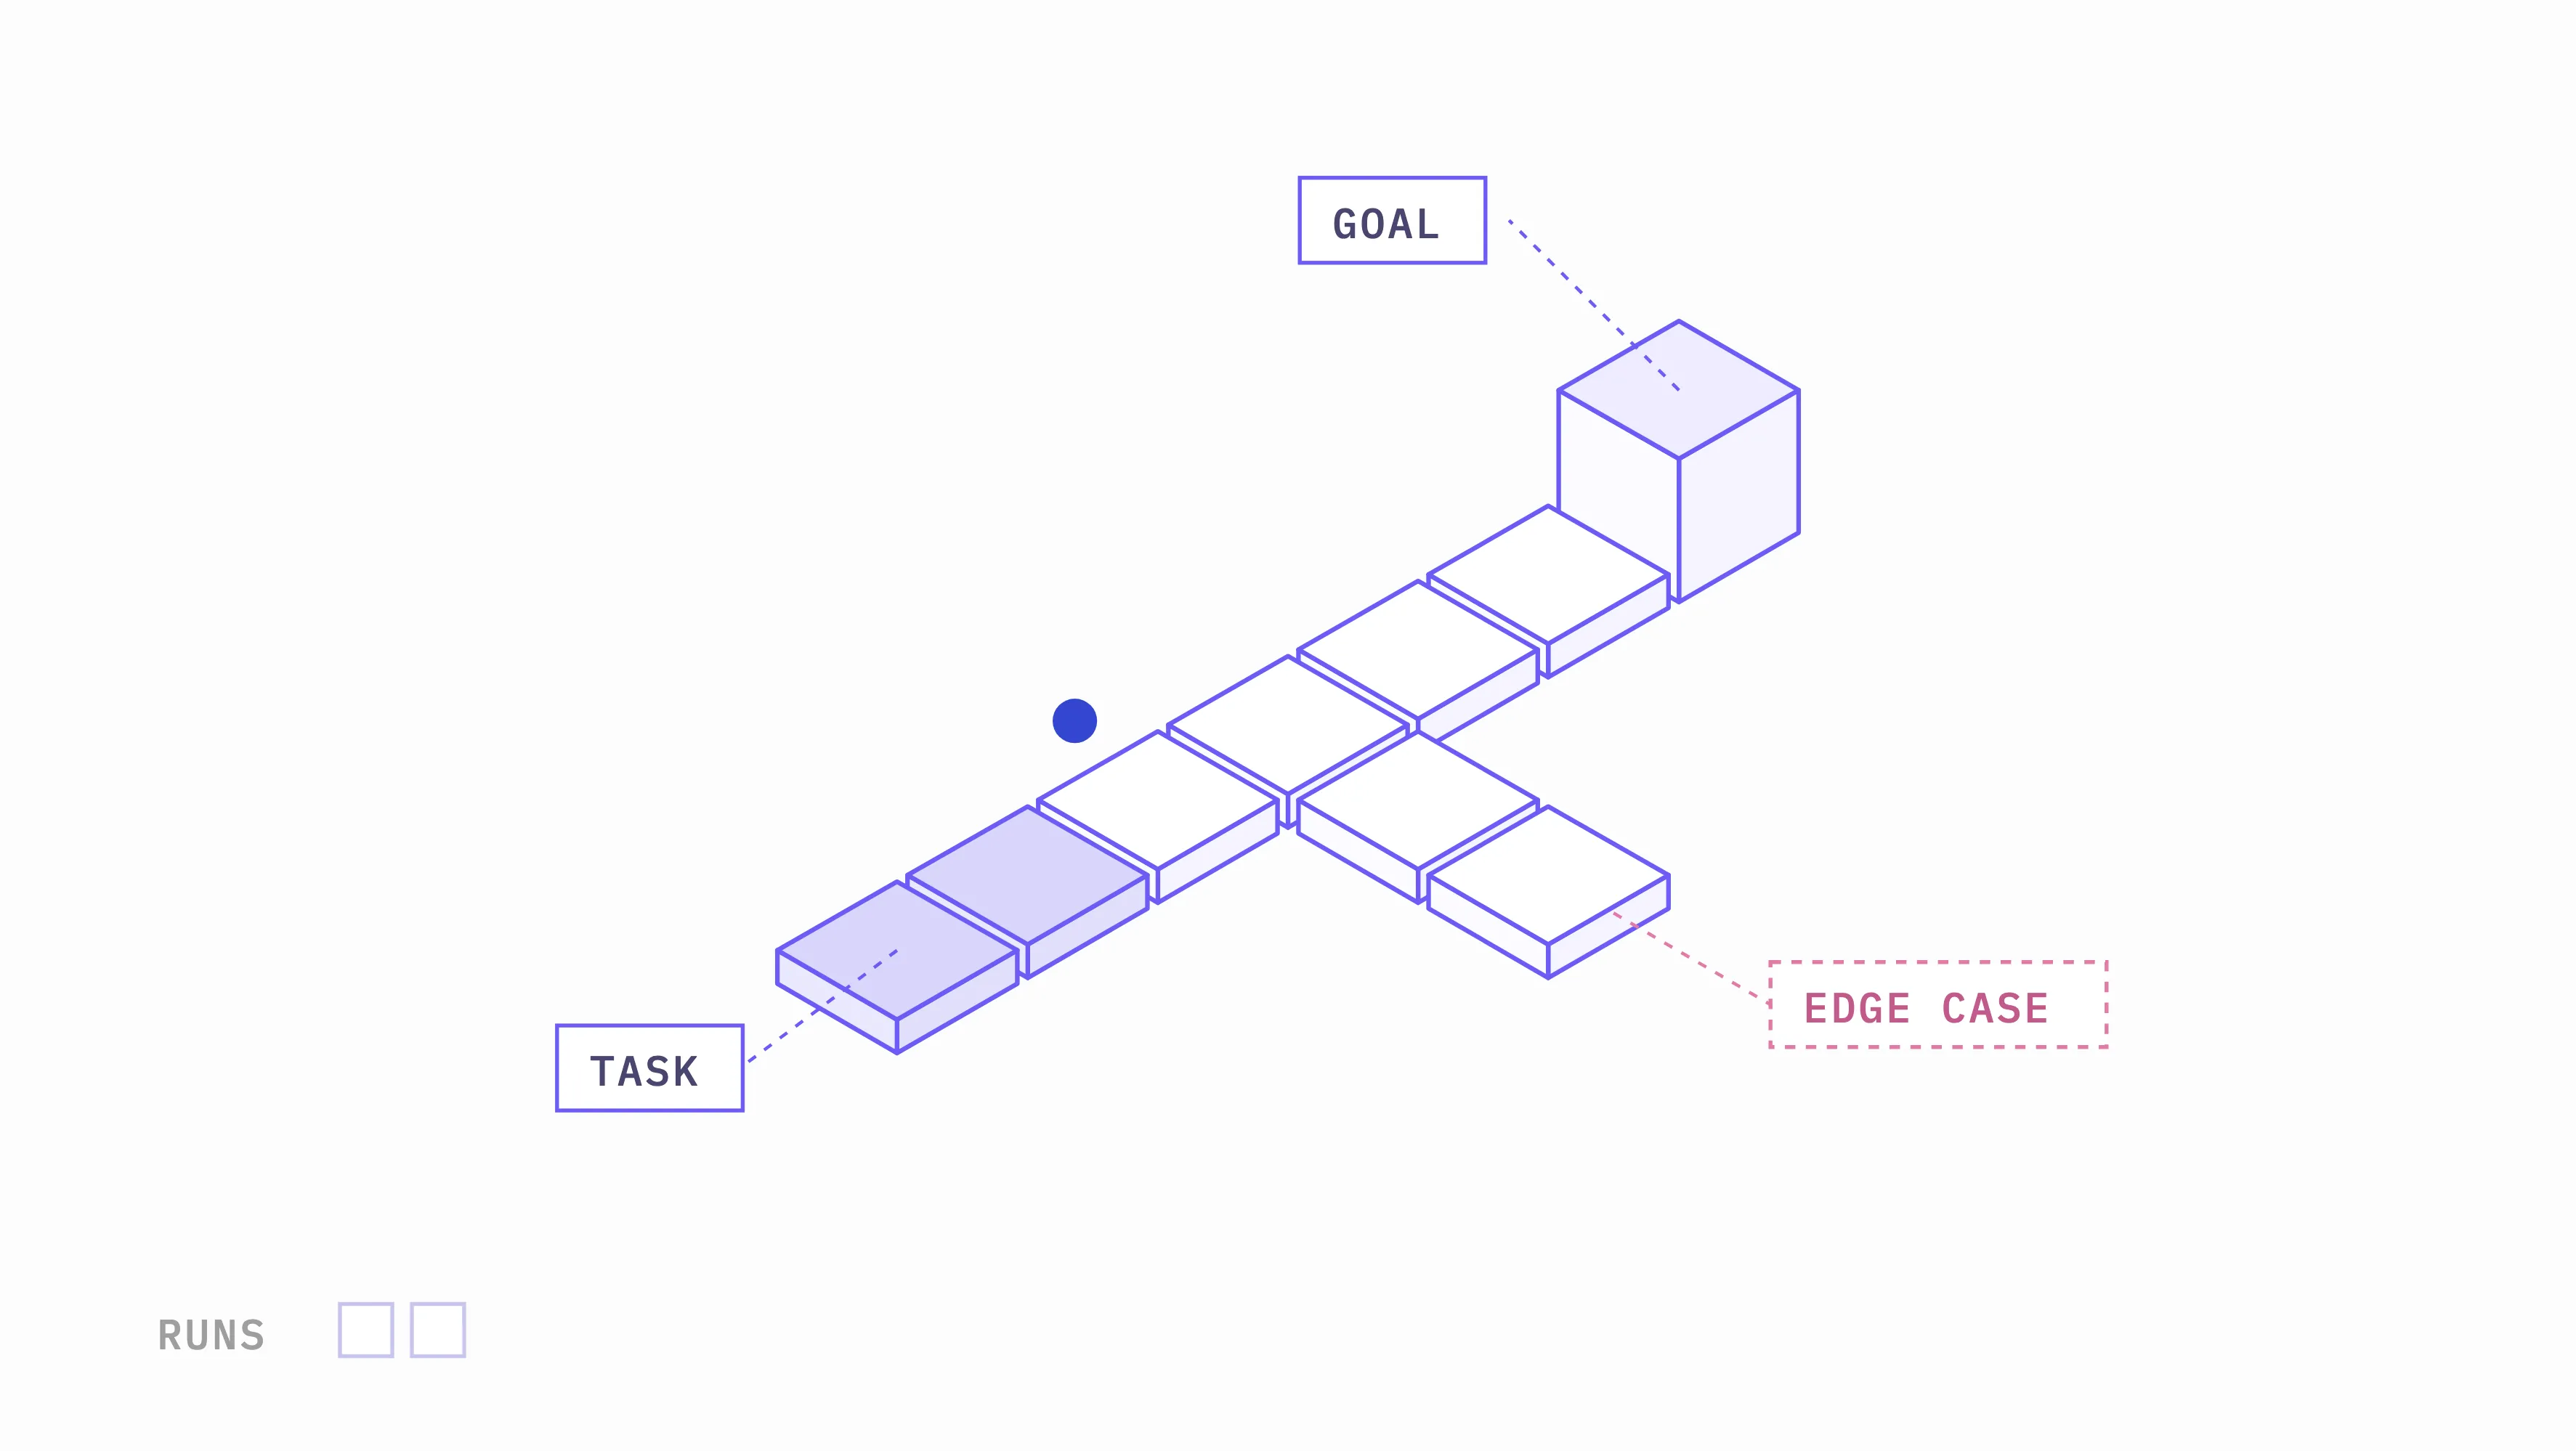
    Lucidic runs thousands of simulations on your hardest cases, systematically searching for the configuration that performs best.

  3. Pull your trained harness

    Your agent loads the optimized prompts and tools with a single training ID. No code changes.

Data

Every trace makes your agent better

Company and production data become datasets and learnings that keep improving your agent over time

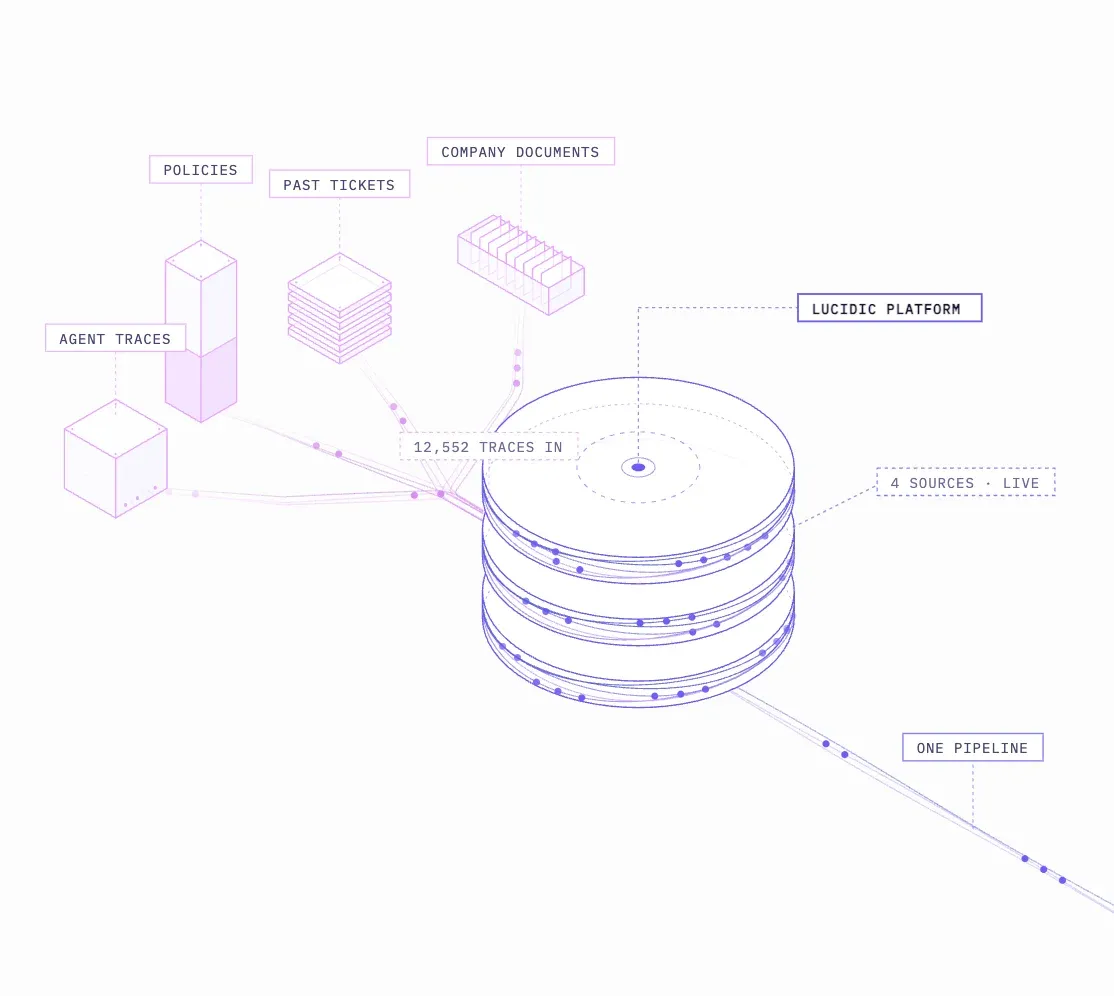
  1. Diagram: agent traces, policies, past tickets and company documents flowing into the Lucidic platform as one pipeline.

    Step 1

    Start with your agent traces, existing datasets, and company context

    We connect to wherever yours live and pull them into one pipeline. No one else has this data, and it shows exactly how your customers use your agent and where it falls short.

    Company documents

    Past tickets

    Policies

    Agent traces

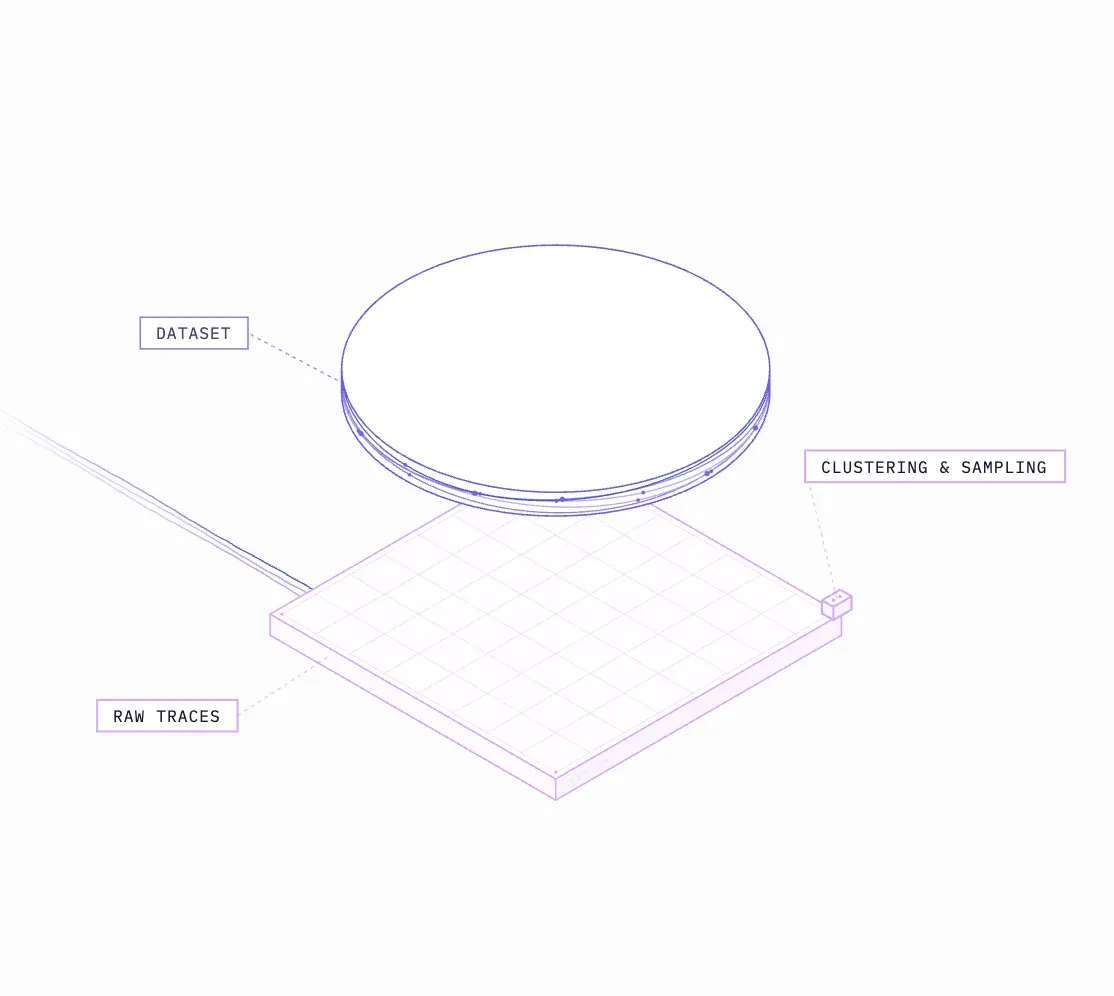
  2. Diagram: thousands of traces grouped into clusters, keeping unusual cases, failures and one example of each pattern.

    Step 2

    Separate the signal from the noise

    Your agent produces thousands of traces, and most are routine. We group similar ones and keep what matters: unusual cases, failures, and one example of each common pattern. The result is a small dataset that shows how your agent really behaves, at a fraction of the cost.

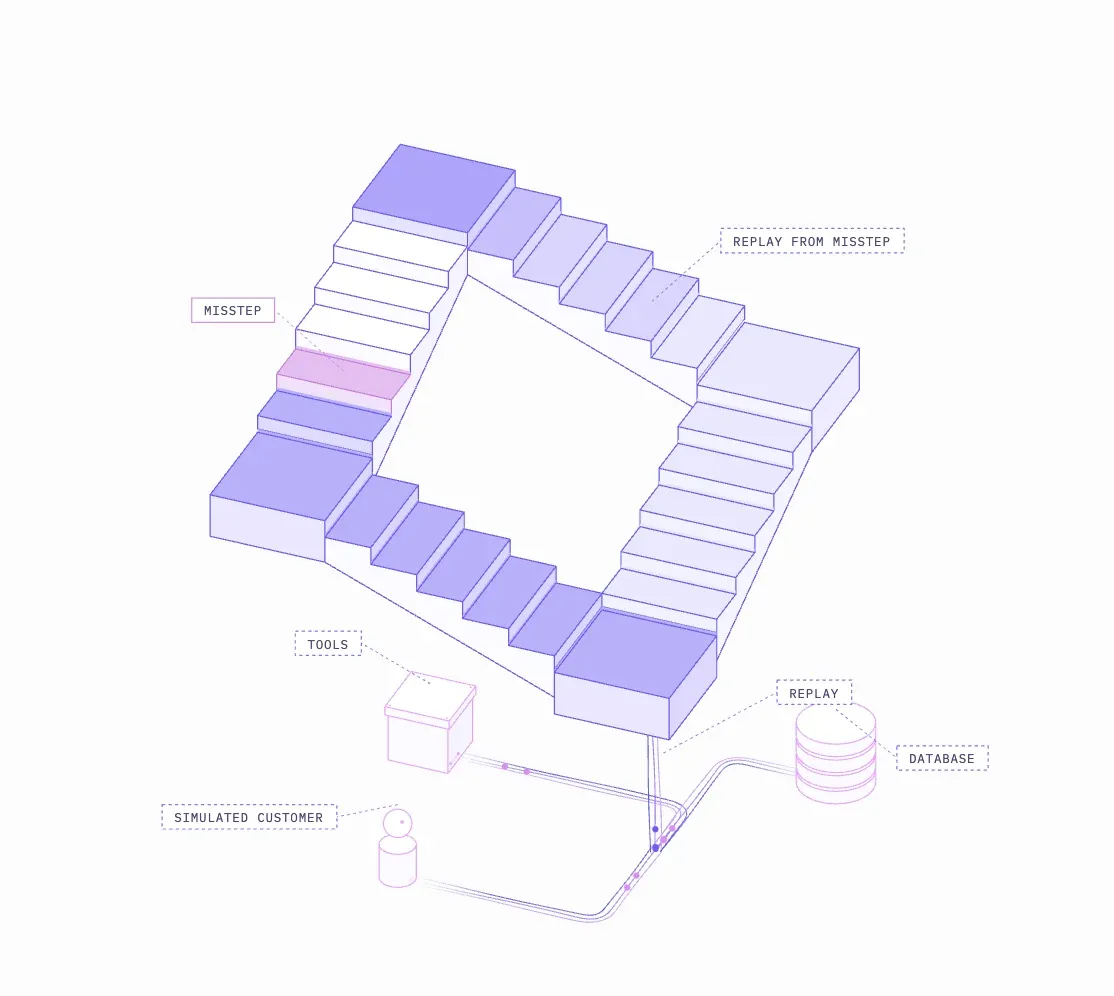
  3. Diagram: a simulated world of tools, a database and a simulated customer, replaying a run from the step where it slipped.

    Step 3

    Set up simulation infrastructure for hill climbing

    We build a replica of your agent's world: its tools, its databases and simulated customers. The agent runs through it step by step, and when a run goes wrong, we go back to the exact step where it slipped. From there we replay with a different choice, again and again, keeping only the paths that score higher, until it reaches the reward.

On a new model release, you can retrain

When a better model comes out, you do not start over: your datasets and learnings carry over to the new model

Talk to us

Case studies

See how we help teams compress months of manual work into overnight runs

View all case studies

ServiceNow evaluated Lucidic's training method on 1,150 tasks drawn from real enterprise workflows

Trained in simulation on half of the tasks, the policy achieved a strict task success rate of 65% on the held-out half, compared with 51.1% for the strongest frontier model.

Read case study: ServiceNow
65%
Strict task success on the held-out half of 1,150 EnterpriseOps-Gym tasks
+13.9 pts
Relative to the strongest frontier model on the public leaderboard
2.3×
Relative to the strongest published RL fine-tune of an open-weight model (28.3%)
Results

Proven on public benchmarks and real enterprise agents

Harvey’s LAB benchmark

Legal work at large law firms

Harvey builds AI for lawyers at large firms. Its Legal Agent Benchmark hands an agent a partner-style instruction and a folder of client documents: draft this agreement, mark up the counterparty’s redline, pull the economic terms from this convertible note.

The output is a review-ready Word document, graded against a rubric written by practicing lawyers. A task passes only if every criterion passes.

  1. Lucidic
    24%
  2. Harvey Tenet fine-tuned Kimi K3
    19.7%
  3. Fine-tuned GLM-5.1 open weights
    12.6%
  4. Claude Fable 5
    11.25%
  5. GPT-5.5
    3.75%

Research

Explore our latest research

Discover insights from our ongoing research into AI agent optimization, performance analysis, and evaluation methodologies